Journal
How to choose the first workflow for an AI pilot
Compare support triage, invoice exceptions and internal search before choosing a bounded test.
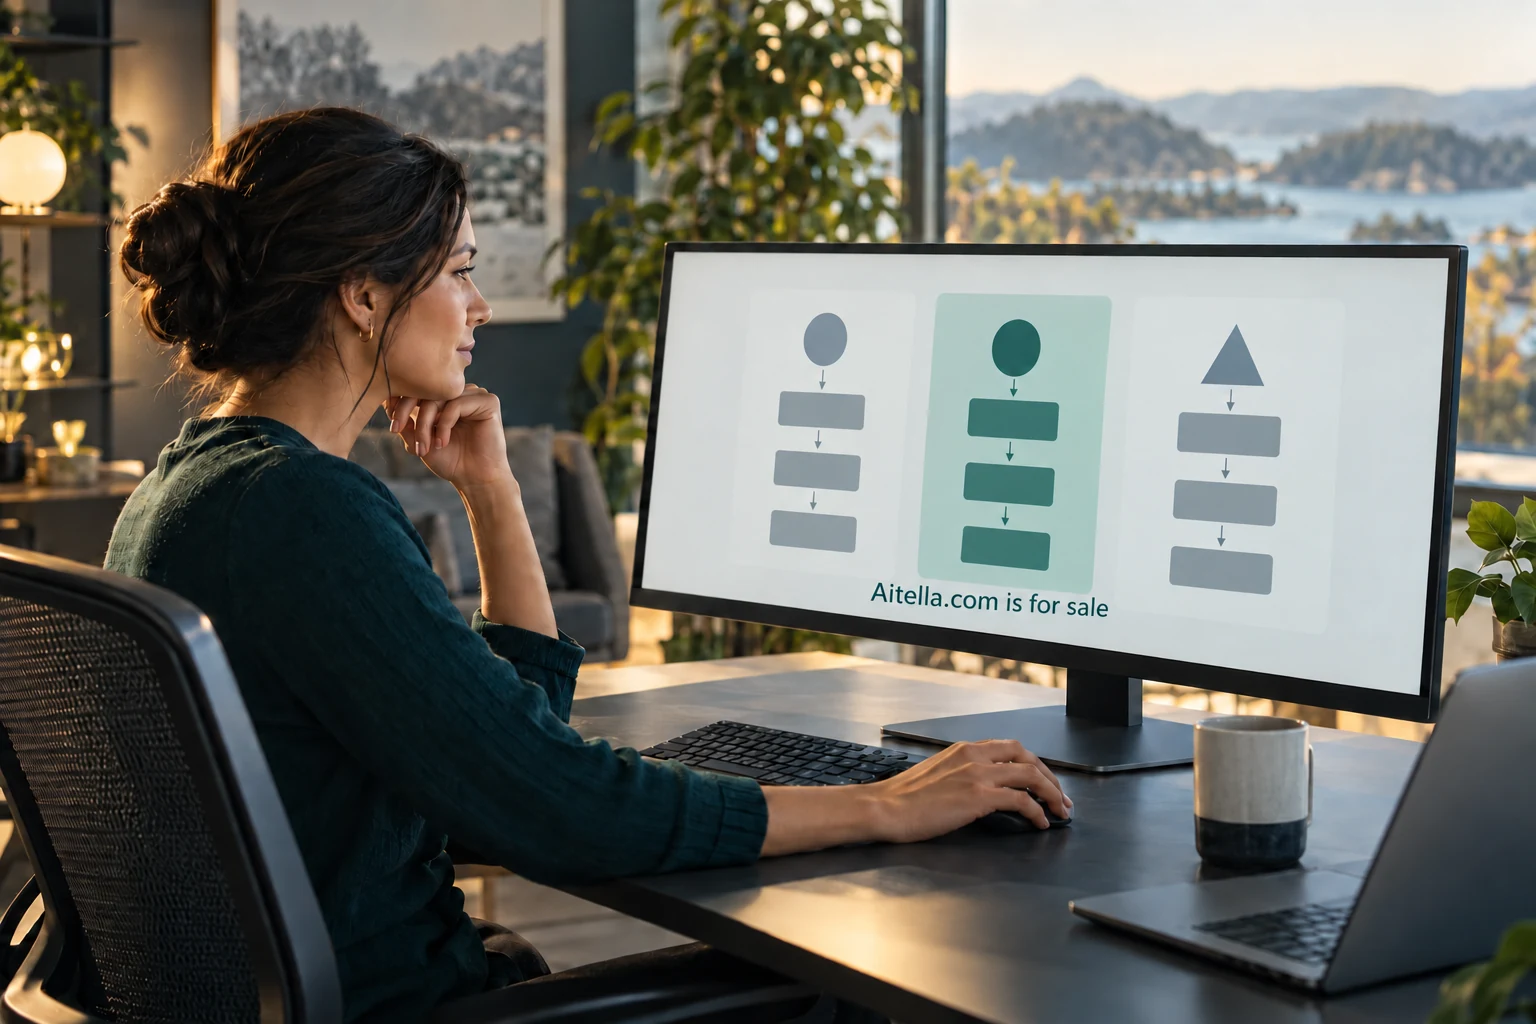
The first AI pilot should answer a small operational question: can assistance improve a repeatable task while leaving the team able to understand and control the result? Choosing that task deserves more attention than choosing a demonstration. An impressive output can hide missing inputs, unclear ownership or review work that makes the process slower. A useful pilot starts with the existing workflow and the person accountable for it.
Map the work before scoring it
Ask the workflow owner to describe a recent case from beginning to end. What starts the task? Which records are needed? Who makes the decision, and what happens afterward? Where do exceptions go? Record the actual sequence, including informal checks. A process diagram that skips the phone call where someone confirms an ambiguous invoice will make the proposed automation look simpler than it is.
Then gather several examples with permission. Include routine cases, a difficult case and a case that was rejected or escalated. The purpose is to understand variation. If the team cannot explain why those cases received different outcomes, it may not yet have a stable decision process to evaluate. Clarifying that process can be valuable work before any AI component is introduced.
Define the boundary in an ordinary sentence. For example: the assistant drafts a category and routing suggestion for incoming support requests, and a coordinator approves the destination. That sentence identifies an input, an output and a human decision. It also distinguishes assistance from authority to send a customer response, change an account or issue a refund.
Use a simple comparison sheet
Score each candidate from one to three on five questions. Are inputs available and permitted? Can reviewers determine whether the output is correct? Does the task recur often enough to provide examples? Can errors be contained before affecting someone? Is there an owner who can participate? A three means favorable conditions; a one means a substantial obstacle. The numbers are a discussion aid, not a validated predictive model.
Do not let the total erase a serious problem. A candidate with plentiful examples but no lawful or permitted access to its data is not ready. A task with no accountable reviewer should not win because it is frequent. Mark these as prerequisite failures and resolve them first. The comparison sheet should expose reasons for choosing a pilot, rather than produce a winner automatically.
Add a short note beside each score. Inputs may be available only through manual exports. Correctness may be easy for common cases but hard for ambiguous ones. An owner may be enthusiastic but unavailable during the proposed pilot period. These details often matter more than the arithmetic and help the team agree on a realistic scope.
Compare support triage
Support triage has a recognizable input: an incoming request. An assistant could suggest a category, urgency and team, while a coordinator reviews the route. The evaluation set can include requests with several topics, incomplete information and misleading urgency language. Reviewers should assess the routing decision rather than simply checking whether the summary is fluent.
The attractive feature is a potentially clear review step before the request is assigned. The complication is that category boundaries may be inconsistent or change between teams. If historic labels reflect habits rather than agreed rules, copying them is not necessarily success. The owner should define the current routing policy and identify examples where more than one destination is reasonable.
A first pilot could make suggestions without sending replies or changing customer records. The team records corrections and the reason for each one. If the assistant repeatedly misses urgent cases, that defect may outweigh convenience on ordinary requests. The pilot needs separate reporting for those consequential errors instead of averaging them into a broad accuracy score.
Compare invoice exceptions
Invoice exceptions offer structured records and concrete discrepancies, such as a quantity that differs from the purchase order. An assistant might assemble the invoice, order and receipt into a review packet. Correctness includes accurate extraction and the right match between documents. The reviewer remains responsible for approval, investigation or rejection.
Access and integration can be the main obstacle. Records may be spread across systems, supplier names may vary and receipts may arrive late. A model cannot repair missing operational data simply by generating a confident explanation. The pilot should include an incomplete state and a route for requesting more information.
This candidate may suit a team with stable records and a committed purchasing owner. It may be unsuitable for a first pilot if matching documents requires extensive integration work before evaluation can begin. A prepared packet can still be valuable without payment authority, making a read-only or draft-only scope a reasonable starting boundary.
Compare internal search
Internal search can help staff find approved material and draft an answer with source links. It may seem low risk because it does not change another system, but a wrong answer can still mislead someone. The intended users and subject matter matter. A casual project lookup differs from advice used for a consequential customer or personnel decision.
The evaluation set should include questions with a clear source, questions with conflicting sources and questions the collection cannot answer. Check whether the answer cites relevant passages and whether the cited document is current. A correct-looking answer backed by an irrelevant page should fail the review. Access controls must also prevent a user from retrieving material they are not allowed to see.
Internal search may be a good first candidate when the source collection is maintained and the answer remains a draft for review. It becomes harder when documents have no owners or obsolete guidance is indistinguishable from current policy. The pilot may first need a smaller approved collection rather than a search box over every company file.
Decide what the pilot will prove
After comparison, choose one candidate and write a testable question. For support triage, it might be whether reviewers can approve a suggested route with fewer corrections than the current method requires. For invoice exceptions, it might be whether prepared packets include the evidence needed for a decision. For search, it might be whether staff can verify answers from current sources. Each asks about the workflow rather than the model in isolation.
Create a permissioned evaluation set before tuning the assistant. Keep some cases separate for later checks and record the current process as a baseline. OpenAI's evaluation guide describes a structured approach using evaluation data and criteria. That general approach can inform a pilot, while the team defines criteria appropriate to its own task and tools.
The owner should agree on stop conditions, review roles and the permitted actions before the first live case. Schedule a short review of corrections and unresolved cases. The first workflow is well chosen when the team can learn something useful from a bounded test, including a decision that the assisted version is not ready. Map the task with its owner, then choose the smallest pilot that can answer the operational question.
The domain opportunity
Make Aitella.com part of your next chapter.
The owner reviews acquisition and partnership inquiries individually.
Inquire to purchase